Refresh Knowledge Data
A knowledge is only as good as the data it indexed. This page explains how to keep it current — both with scheduled refreshes and with manual operations — and what to do when things go wrong.
What happens during a refresh
For every source configured on the knowledge:
- The source is read — the folder is scanned, the uploaded files are listed, the web pages are fetched.
- Each document is compared with the state of the last refresh:
- Files (uploaded files, a folder on the server): a file whose modification time and size are unchanged is not even opened again.
- Web pages: the page is fetched, but only embedded again if its text has changed.
- New and changed documents are split into chunks, embedded (sent to the knowledge's embedding model) and stored — replacing the old chunks of the same document.
- Documents that no longer exist (file deleted, page gone, source removed) are removed from the index.
Only what changed costs embedding calls. The job log sums it up, for example Documents: 2 new, 1 changed, 1 removed, 140 unchanged, followed by the names.
The refresh works on a copy of the index. Searches keep using the previous state until the refresh has finished successfully; a cancelled or failed refresh changes nothing.
Full rebuild
Everything is read and embedded again when:
- the knowledge is refreshed for the first time,
- its model was changed (other embeddings), or
- you click Re-read everything in the toolbar.
A full rebuild is the fix if search results look wrong after big changes, and the way to pick up improvements in how documents are read.
Refresh modes
| Mode | Triggered by | When to use |
|---|---|---|
| On change | Automatic Refresh set to Manual / On Change: a file is uploaded, deleted or changed in the knowledge's file upload or in its folder on the server. | Default for uploaded files and folders. The refresh starts 30 seconds after the last change, so uploading ten files results in one refresh. |
| Scheduled | Automatic Refresh set to an interval or a time (every 2 hours … once a week). | For web pages and folders that change without anyone uploading — scheduled refreshes also pick up changes the platform cannot see. |
| Manual | Update (changes only) or Re-read everything in the editor toolbar. | After adding a source, while testing, or to force a full rebuild. |
Web pages are not watched — only a schedule or a manual refresh picks up their changes.
How long does a refresh take
A few rough numbers:
- Small knowledge (a folder with a dozen documents): seconds.
- Mid-size knowledge (a hundred documents or a couple of websites): a few minutes.
- Large knowledge (thousands of documents): tens of minutes to hours. First-time indexing is the slowest; incremental refreshes are much faster.
The Jobs view shows progress and an estimated time for in-flight refreshes.
📷 SCREENSHOT: A refresh in progress in the Jobs view, with the percentage of processed chunks visible.
Manual refresh — step by step
- Open the knowledge in the editor.
- Click Update (changes only) in the toolbar — or Re-read everything for a full rebuild.
- The status badge changes to Refreshing. You can leave the page — the refresh runs in the background.
- Open the Jobs view to see the progress.
- When the refresh completes, the badge changes to Up to date and the Last refreshed timestamp updates.
Looking at past refreshes
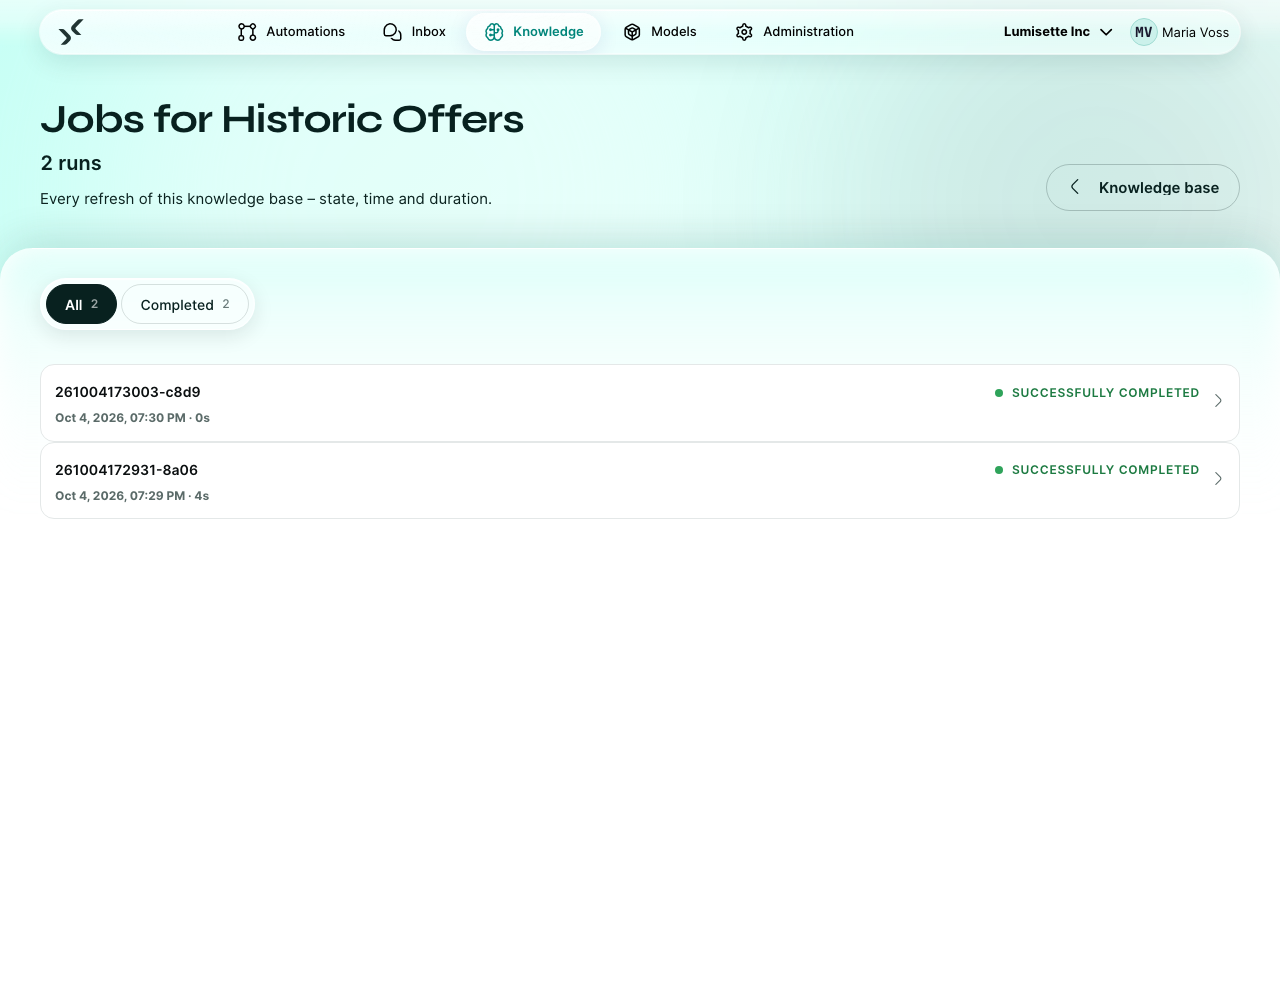
Each refresh is a job — the same concept used for workflows. Open the Jobs view from inside the knowledge editor to see:
- Start and end time, duration.
- A status — completed, failed, partial.
- Number of chunks processed, added, removed.
- The log of any sources that failed.
When a refresh fails
Common causes:
- Source unreachable. A URL is down, a folder is no longer mounted, a database is unavailable. The refresh log identifies which source failed; other sources continue.
- Authentication. Credentials in the source configuration have changed or expired.
- Embedding model unavailable. The connected model's provider is down or rate-limited.
- Content too big. A single source contains a document the platform cannot process. The log identifies which file.
If the cause is transient (network blip, rate limit), the next scheduled refresh recovers automatically. For persistent issues, edit the source or the embedding model.
Cost considerations
Every embedded chunk costs one call to the embedding model. Because only new and changed documents are embedded, a refresh of an unchanged knowledge costs nothing but the reading; a full rebuild costs as much as the first indexing.
A few tips to keep cost reasonable:
- Use the longest sensible refresh interval for web pages. Hourly is rarely needed; daily is enough for most content.
- Use Re-read everything sparingly — only after model changes or when results look wrong.
- Split content between knowledges that change often and knowledges that change rarely. Refresh policies are per-knowledge.
- Watch Metrics → Consumption — embeddings appear as their own line item.
Recommendations
- ✅ Set refresh policies that match how often the source data actually changes, not how often you wish it did.
- ✅ Run a manual refresh after editing the configuration (for example after adding a source) — it is picked up at the next refresh otherwise.
- ✅ Inspect the Jobs view at least once a week. Quietly failing sources are a common cause of "the AI doesn't know about X".
- ⚠️ Refreshes overlap. If a refresh takes longer than the interval (say a daily refresh takes 25 hours), the next one is queued. This is harmless but counts as wasted effort — increase the interval.
- ⚠️ Removing a source removes its content from the index. If the same content was added via a second source, it stays. Surprising at first, correct on reflection.
- ❌ Do not trigger refreshes from very short cron schedules ("every minute"). Embedding models rate-limit and the queue will pile up.
What to do next
- Create and Edit Knowledge Bases — the configuration side.
- Metrics → Consumption — track refresh cost.